Data warehouse integrations are available as a premium add-on for Kameleoon’s Web Experimentation and Feature Experimentation module. For more information, contact your Customer Success Manager.
- Lets you target visitors with audiences built from your Databricks tables.
- Lets you use Databricks conversions as goal metrics in experiment results.
- Databricks as a source: Each Data Ingestion Task runs at the Frequency you set when you create it, for example per day. Kameleoon polls goal queries every hour and merges the collected conversions into experiment results once per day. See Data Ingestion Tasks.
- Databricks as a destination: Kameleoon sends exposure events to Databricks whenever one of your experiments exposes a visitor. See how the destination works.
Prerequisites
To configure this integration, you need the following information:- Databricks personal access token (PAT)
- Proper access to create Databricks schema and grant access.
Setup
1. Create a personal access token (PAT)
Kameleoon will authenticate to your Databricks SQL warehouse with a personal access token. You should create a Databricks service principal and then create a PAT for that service account. Once you create a service principal, you can generate a PAT with the Databricks CLI, using the Service Principal “Application Id” that you can find in the Service Principal management page of the Databricks UI.2. Create Kameleoon schemas and grant Unity Catalog access
For both source and destination, give the service principal CAN USE on the Databricks SQL warehouse in its Permissions settings. For Unity Catalog, grant access to each catalog Kameleoon uses:CREATE SCHEMA on the catalog.
When using Databricks as a source
For audience ingestion, create a dedicated schema in the catalog that contains the data Kameleoon polls. Name itkameleoon_configuration. Kameleoon creates, reads, and removes audience snapshot tables in this schema. Grant the service principal access to this schema only. It doesn’t need write access to your source tables.
MODIFY also requires SELECT on the tables.
SELECT and MODIFY on those tables. The following schema-level grants also cover current and future event tables in this dedicated schema:
{Service Principal Application Id} in these commands with your service principal’s application ID.
You can omit the
my_catalog prefix when running queries directly in the necessary catalog.3. Grant read access to your data
For Databricks as a source, grant access only to the customer tables or views used by your audience and goal queries. First grant usage on their schema:SELECT on each required table or view. Alternatively, grant it on the schema if Kameleoon should read all current and future tables and views in it:
SELECT or MODIFY on your customer-data schema. If you use goals without audience ingestion, Kameleoon only reads your query results and doesn’t create audience snapshots.
4. Enter your credentials in Kameleoon
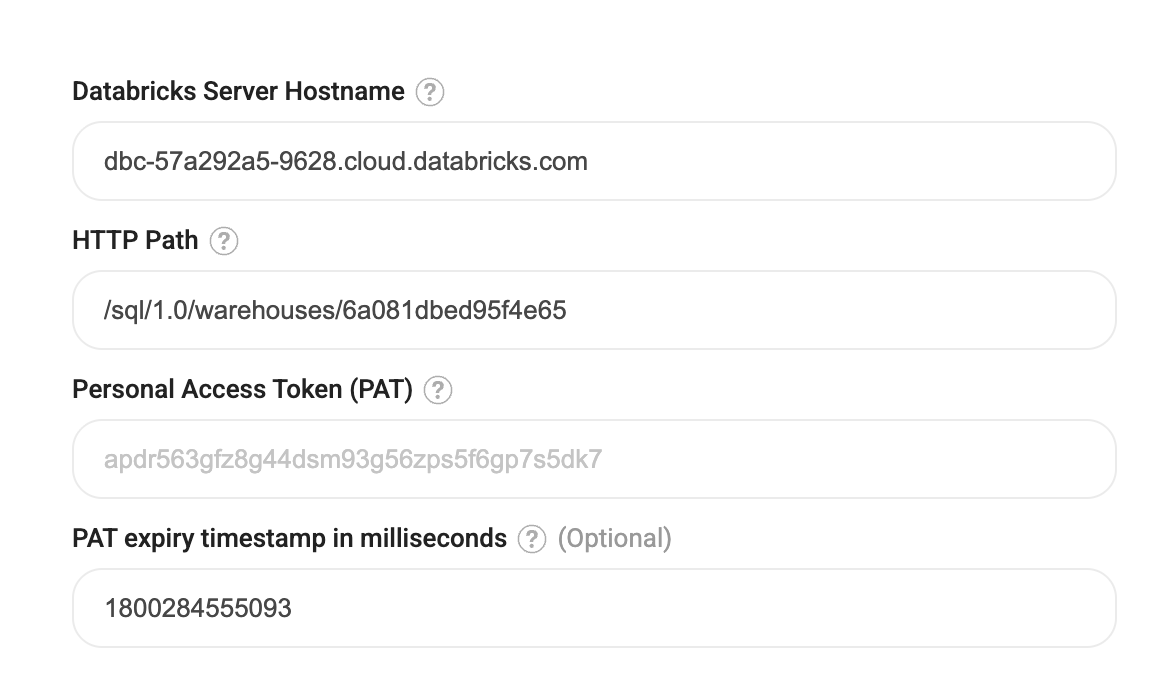
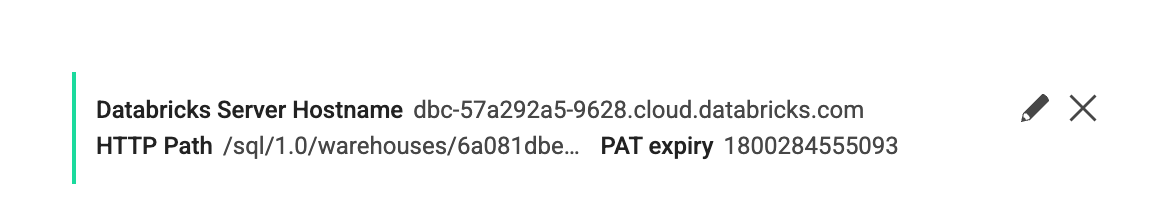
In the Databricks integration settings of your project in Kameleoon, complete the Credentials fields:- Databricks Server Hostname: the server hostname of your Databricks workspace.
- HTTP Path: the path to your Databricks SQL warehouse.
- Personal Access Token (PAT): the token you created in step 1.
- PAT expiry timestamp in milliseconds (optional): the expiry time of the token, as a Unix timestamp in milliseconds. This field is optional, and you enter the value yourself.