

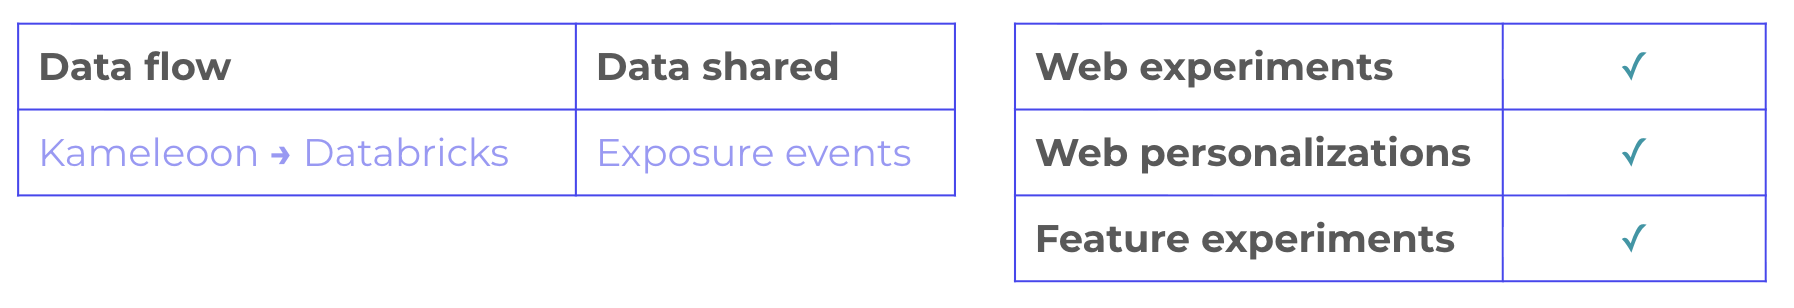
Activate Databricks as a destination
To activate Databricks as a destination:- Click Use Databricks as a destination.
- Databricks catalog: name of the Databricks “catalog” that contains the Kameleoon schema to write to (the top level folder).
- Schema: Schema where Kameleoon writes its event table, for example
kameleoon_events.

What “Use Databricks as a destination” does
After you enable Use Databricks as a destination, Kameleoon writes every experiment exposure to Databricks. Kameleoon stores events in thekameleoon_events schema of your Databricks catalog. This catalog is the one you set up during setup, with write access granted to Kameleoon’s service principal. Kameleoon saves the data in a table named kameleoon_experiment_event and writes each exposure as one row. Your own Databricks settings control how long Databricks retains these rows.
An exposure reaches your Databricks table in two steps: a web, mobile or server SDK sends the exposure payload to Kameleoon’s Ingestion API, and Kameleoon then writes it to Databricks with an authenticated insert.
Kameleoon doesn’t keep a copy of exposure events. It flushes each event to Databricks, so a failed write loses that event. Kameleoon doesn’t retry failed writes, and it doesn’t send notifications when a write fails.
The SQL schema of this table is the following:
custom_visitor_id from the Cross Device Reconciliation custom data, if you set it.