

Data warehouse integrations are available as a premium add-on for the Web Experimentation and Feature Experimentation module. For more information, contact your Customer Success Manager.
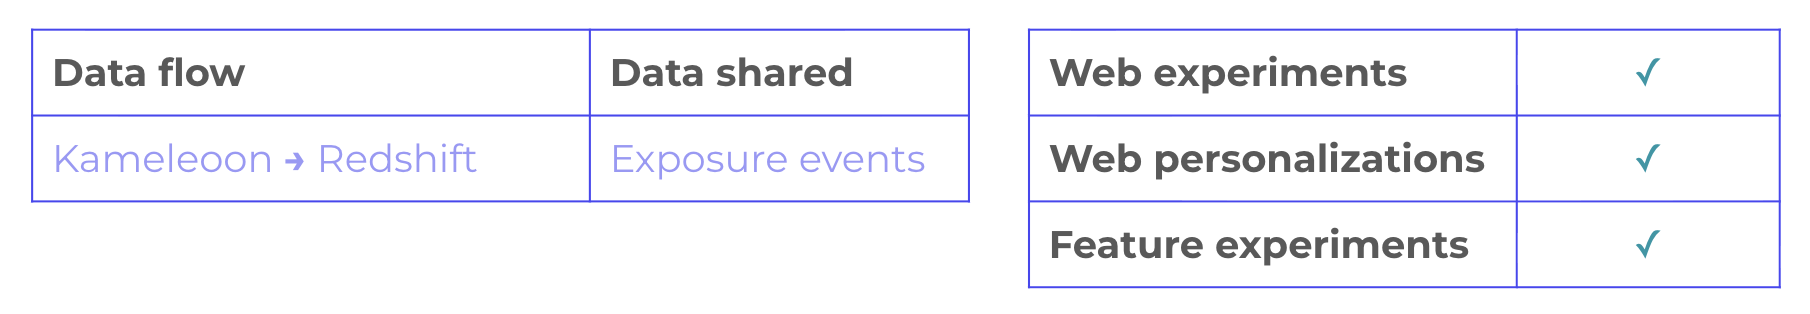
Activate Amazon Redshift as a destination
To activate Amazon Redshift as a destination:- Click Use Amazon Redshift as a destination.
- Choose your cluster type: Provisioned or Serverless.

- Enter the fields for your cluster type:
- For the Provisioned cluster type:
- Redshift cluster ID: the identifier of your Amazon Redshift cluster
- S3 bucket name: the full name of an Amazon S3 bucket for staging streamed events before periodic bulk loading into Redshift. The policy attached to the AWS role you set up in Setting up Amazon Redshift must grant access to this bucket
- Redshift AWS region: the region code where your Redshift cluster resides. Find this code in your AWS console. Example:
eu-west-1 - Database: the name of the Redshift database where Kameleoon writes the events
- For the Serverless cluster type:
- Redshift serverless workgroup: your workgroup’s name
- S3 bucket name: the full name of an Amazon S3 bucket for staging streamed events before periodic bulk loading into Redshift. The policy attached to the AWS role you set up in Setting up Amazon Redshift must grant access to this bucket
- Redshift AWS region: the region code where your Redshift workgroup resides. Find this code in your AWS console. Example:
eu-west-1 - Database: the name of the Redshift database where Kameleoon writes the events
- For the Provisioned cluster type:
- Click Confirm.
- Click Validate to save your changes.
What Use Amazon Redshift as a destination does
Kameleoon first stages the events in the S3 bucket you provide, then loads them into Redshift periodically. Kameleoon stores events in thekameleoon_events schema of your {database} database, the Redshift database that you enter in the destination settings. You create this schema during setup, and the Kameleoon IAM role needs write access to it. Kameleoon saves the data in a table named kameleoon_experiment_event.
The SQL schema of this table is the following:
custom_visitor_id from the Cross Device Reconciliation custom data, if you set it.